Create a block explorer
What it is
Creating a block explorer means indexing every block, transaction, log and trace of a chain, from its first block, into a database where anyone can look up an address, a transaction or a block, and reading live balances and contract state over RPC.
Chain teams need one when mainnet opens and explorer companies add chains often, because users, wallets and support teams check every transfer there, and an explorer that lags or still shows a block the chain dropped gives them the wrong answer.
Goldsky streams the chain’s history and each new block into your database with Turbo Pipelines, decoding contract events and correcting rows after reorgs, and serves live reads through Edge RPC, while contract verification, search and the pages stay with you.
Who it’s for
Block explorer companies, chain teams launching an explorer with mainnet, and wallets and analytics firms that run their own explorer pages; the RPC and indexed data a new chain needs at launch is archive RPC and indexing for a new chain.
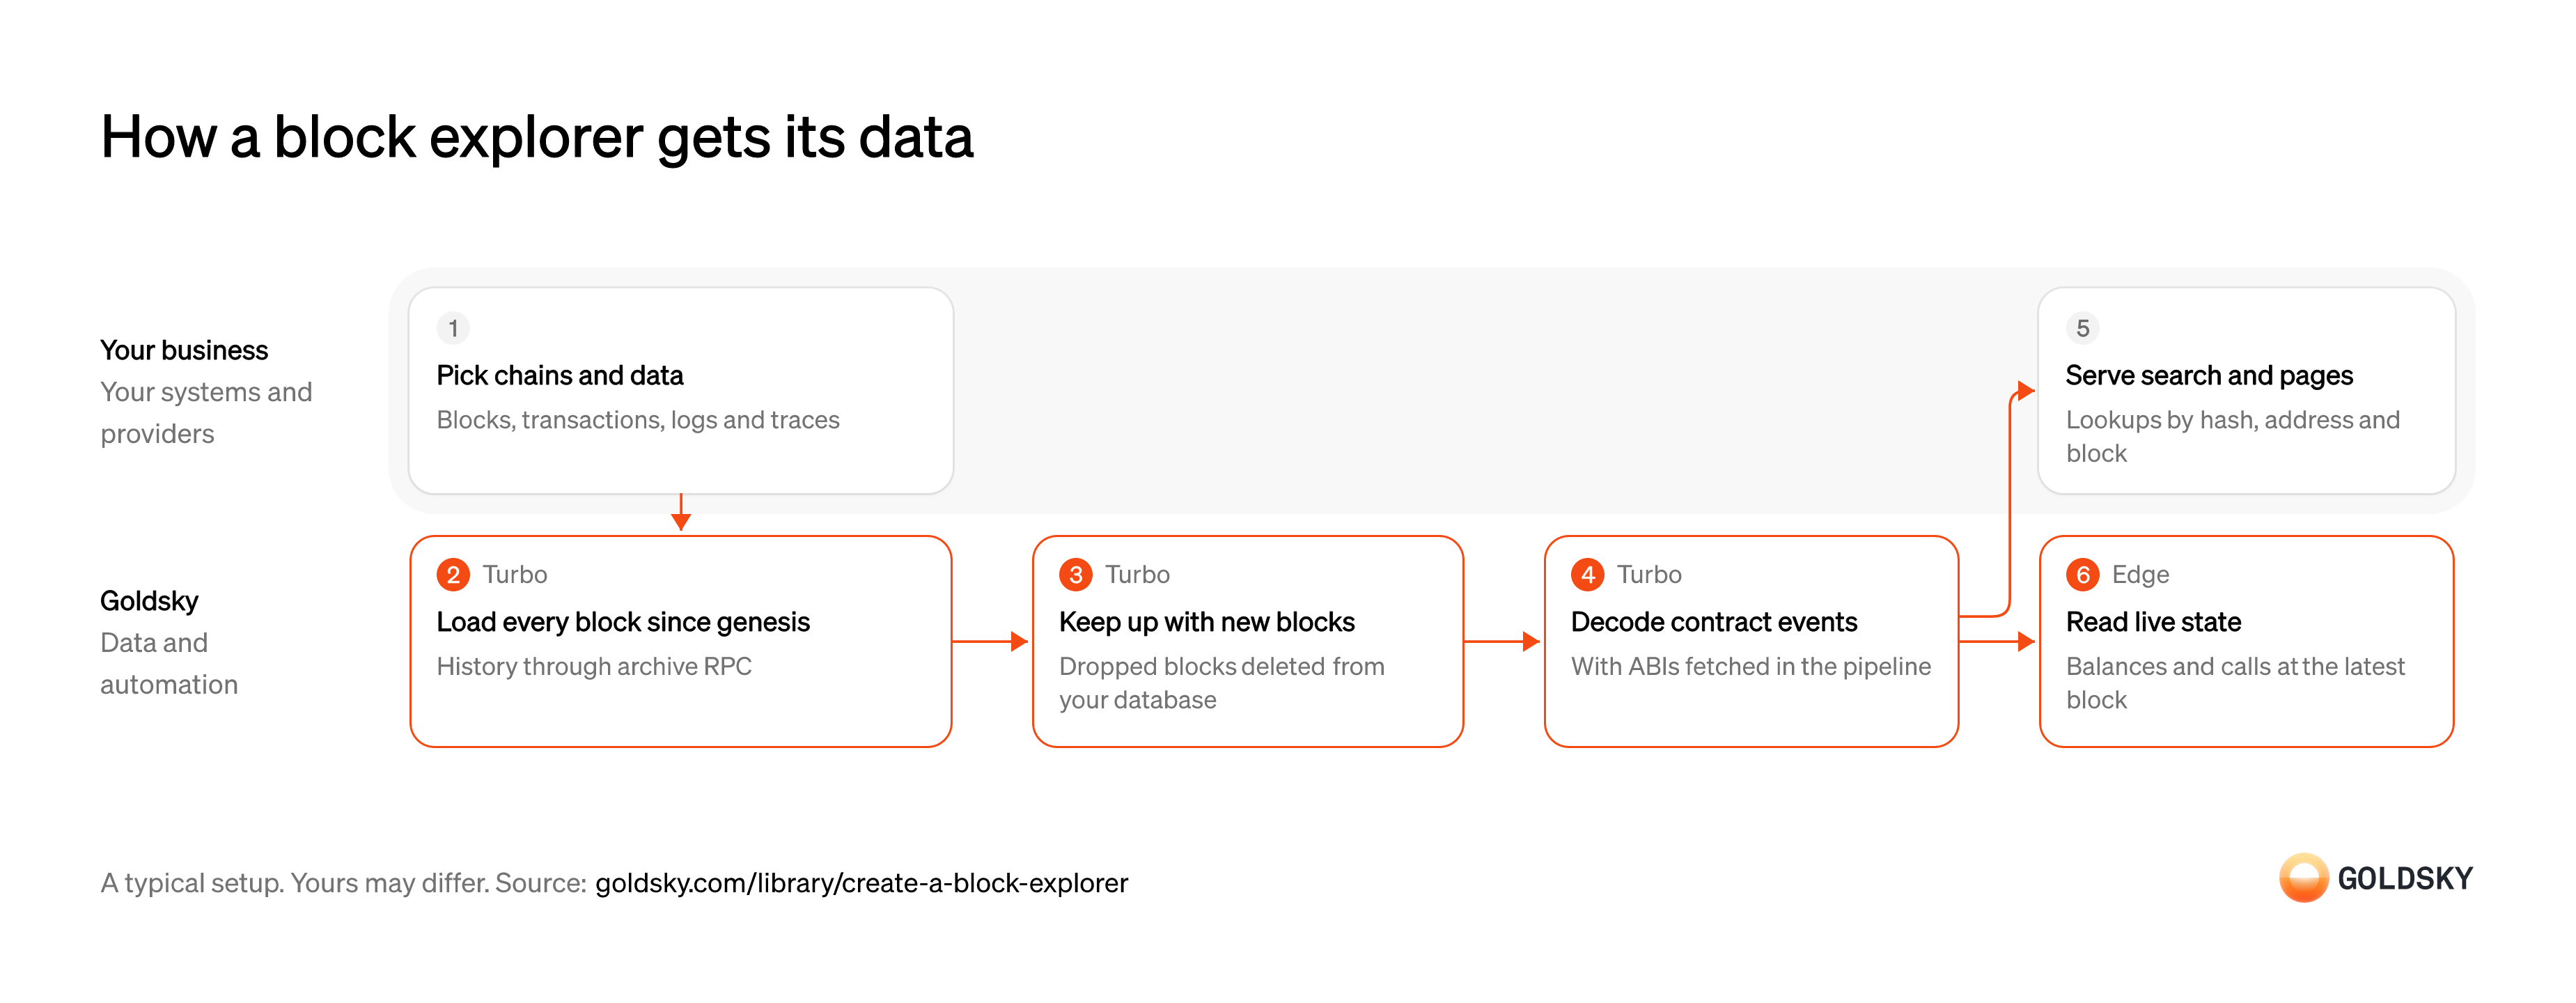
How a block explorer gets its data
The diagram follows one chain from choosing what to index to the pages your explorer serves, and shows who does each step. Your setup may differ.
Pick the chains and data to index
An explorer can only show what it has indexed, so start from what users look up.
List the chains, and for each the blocks, transactions, logs and traces you’ll show. Traces record internal calls between contracts, and leaving them out means value moved by a contract never appears on an address page.
Load every block since genesis
Handled by Goldsky TurboUsers look up old transactions as often as new ones, so the index has to start at the first block.
An index that starts late shows addresses with missing transactions. A backfill from the first block needs archive data, because ordinary nodes drop old state.
Goldsky’s Turbo Pipelines Edge EVM datasets stream blocks, transactions, logs and traces from any EVM chain through Edge RPC, which routes historical requests to archive nodes, starting from
Stream any EVM chain (opens in a new tab)earliestand carrying on at the chain tip.Keep up with new blocks and reorgs
Handled by Goldsky TurboAn explorer that lags, or still shows a block the chain dropped, gives users the wrong answer.
New blocks have to land within moments, and blocks the chain replaces in a reorg have to disappear from search. Rows keyed on a block hash or log ID let each correction update the right row.
Each Edge EVM row carries a
See how reorgs reach your database (opens in a new tab)_gs_opcolumn,cfor an insert anddfor a delete when a reorg orphans it, and a Postgres sink with aprimary_keyapplies both, so the database converges to the canonical chain.Decode contract events
Handled by Goldsky TurboUsers want to read “transfer of 100 tokens to this address”, not encoded log data.
Each log and call is decoded with its contract’s ABI, so pages show event names and fields. ABIs come from contracts verified on your explorer or published by their teams, and a contract verified later still needs its past events decoded, or its early history stays raw.
Turbo Pipelines decodes logs with
Decode contract events in a pipeline (opens in a new tab)evm_log_decodeand calls withevm_trace_decodein a SQL transform, using ABIs it fetches with_gs_fetch_abi, so rows land in your database already decoded. Keeping the raw logs as well lets you decode a contract verified later from rows you already hold.Serve search and pages
An explorer is only useful if any address, transaction or block comes up quickly.
Your database indexes the tables for lookups by hash, address and block, and your API serves the pages. Balances and contract state change with every block, so read them live rather than from the index.
Read live state over RPC
Handled by Goldsky EdgeCurrent balances and contract reads come straight from the chain.
Pages call the chain for balances, contract code and reads at the latest block. A single provider that falls behind leaves every page showing stale numbers.
With Goldsky, Edge RPC serves those calls over HTTPS, fails over across several upstream providers and cross-validates their responses.
See how Edge RPC fails over (opens in a new tab)
What you control
- Your team
- Pick the chains and data to index
- Serve search and pages
Questions and answers
How do you create a block explorer?
You create a block explorer by indexing every block, transaction, log and trace of a chain into a database, decoding contract events with their ABIs, and serving search and pages from that database, with live balances read over RPC. The index has to start at the chain’s first block and follow reorgs, so a lookup never shows a transaction the chain dropped. Open-source explorers bundle these pieces; building your own lets you choose the database and the pages.
Security and deployment
- SOC 2 Type IIIndependently audited security controls.
- Dedicated infrastructureSingle-tenant options for production workloads.
- Data residencyCloud, on-premises or co-located.
More use cases that access chains reliably
- Archive node RPCRead any past state through archive RPC.
- Archive RPC and indexing for a new chainGive a new chain archive RPC and indexing from mainnet day one.
- RPC and indexed data for a payments blockchainProvide RPC and indexed data for a chain run by a fintech.
- Improve RPC uptime and reliability with failoverRun a second data provider behind the incumbent and fail over when it drops data.
- Optimize your RPC endpoints and cut RPC costsAutomatically optimize your RPC endpoints and lower billable calls while keeping your current provider.
- Improve blockchain data API reliability and coverageKeep wallet balances, transfers and token prices arriving when a third-party blockchain data API has an outage, rate limits you, lacks a chain or returns wrong balances.
- Improve subgraph uptime and reliability with failoverKeep app screens up when a hosted subgraph lags, stops syncing or goes down, with a backup to fail queries over to.
- Improve blockchain webhook reliabilityKeep onchain event notifications arriving at your backend, with retries, reorg corrections and a backup feed.
Use cases built the same way
- Replace in-house blockchain ETL and cut its costRetire your own nodes and ETL jobs and load the same chain data tables from a managed pipeline.
- Authorize and capture stablecoin paymentsHold a buyer’s stablecoins in an escrow contract at checkout, capture them to the merchant as orders ship, void what can’t be filled and refund after capture.
- Programmable escrow for B2B stablecoin paymentsHold a buyer’s stablecoin payment until delivery, a milestone or a deadline, then release it to the seller or refund the buyer.
- Cross-chain transfer trackingSee every cross-chain stablecoin transfer as settled, in flight or stalled, and catch the stuck ones.
Create a block explorer with Goldsky
We’ll map it to your systems and show you what Goldsky runs, so your team builds the product, not the pipelines underneath it.
 Robinhood
 HyperEVM
 Arc
 Solana
 Ethereum
 Polymarket
 Base
 Tempo
 Bitcoin