Blockchain ecosystem growth metrics
What are blockchain ecosystem growth metrics?
Blockchain ecosystem growth metrics are the chain metrics a foundation or ecosystem team reports to show its chain is growing: active, new and returning addresses, transactions, fees and usage per app, counted from onchain data and set beside other chains.
Foundations, ecosystem teams and the funds and data providers that cover chains depend on those numbers being counted the same way every month: builders, investors and grant programs compare chains on them, and an onchain analytics dashboard that counts bots overstates growth.
With Goldsky’s Turbo Pipelines, you can stream every transaction on your chain and the chains you compare into your warehouse, or keep daily counts and fees as running totals in Postgres that a live dashboard reads.
Who tracks blockchain ecosystem growth metrics?
Layer 1 and layer 2 foundations, ecosystem and business development teams, and the funds, research firms and data providers that track chains.
How blockchain ecosystem growth metrics are counted
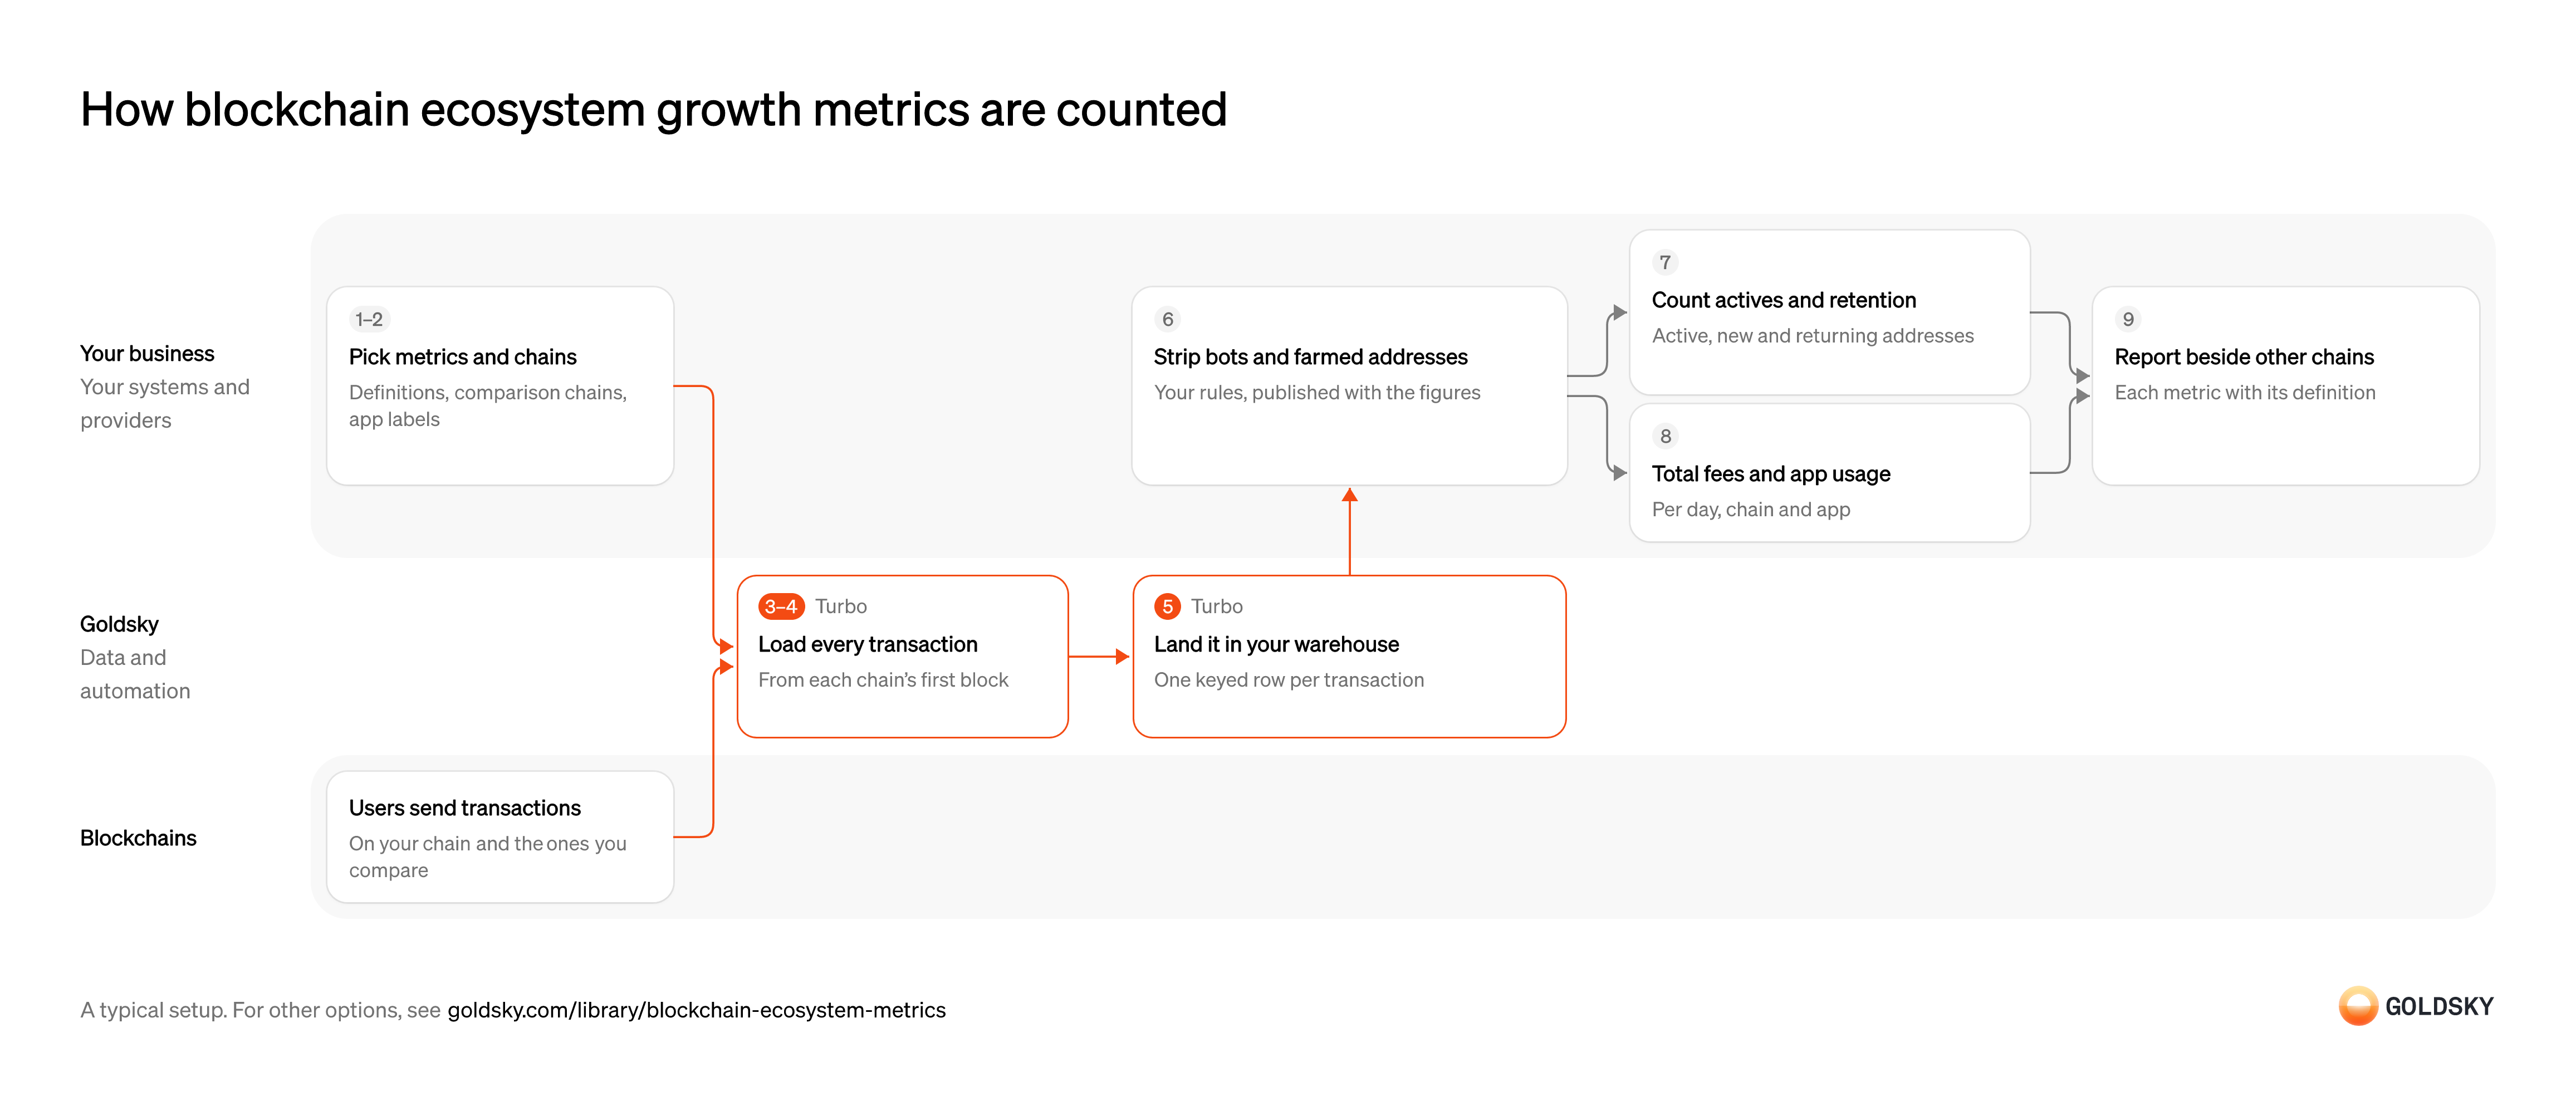
The diagram follows one reporting cycle from defining the metrics to publishing your chain’s growth beside other chains, and shows who does each step. Your setup may differ.
Ways to track blockchain ecosystem growth metrics
Streaming to a warehouse keeps every transaction, so analysts can define cohorts and compare chains over any period; running totals in Postgres keep daily counts per chain, app and address current as each block lands, with no warehouse to run.
- Best for
- Full history and cohorts across several chains
- Products
- Turbo
- Where the figures are worked out
- Your warehouse queries, over every transaction
- A repeated delivery
- Collapsed on each transaction’s key
- Best for
- A live dashboard of one chain, without a warehouse
- Products
- Turbo
- Where the figures are worked out
- Postgres totals updated as each block lands
- A repeated delivery
- Can add to a running total twice
| Usual setupOption 1: Stream to your warehouse | Option 2: Running totals in Postgres | |
|---|---|---|
| Best for | Full history and cohorts across several chains | A live dashboard of one chain, without a warehouse |
| Products | Turbo | Turbo |
| Where the figures are worked out | Your warehouse queries, over every transaction | Postgres totals updated as each block lands |
| A repeated delivery | Collapsed on each transaction’s key | Can add to a running total twice |
Define each metric before counting
Active addresses, users and fees can each be counted several ways, and figures only compare across months and chains when the definition stays fixed.
Decide whether an active address is one that sends a transaction or also one that receives, whether failed transactions count, whether fees include the L1 data fee a rollup pays, and when an address counts as new or returning. Write the definitions down, because a chain that counts receivers looks larger than one that counts senders only.
Pick the comparison chains and label your apps
Growth means something next to a baseline, and usage per app needs to know which contracts belong to which app.
Choose the chains you compare against and one start date for all of them, and map the contracts on your chain to the apps that deployed them. A contract nobody labeled shows up as unknown usage instead of under its app.
Load every transaction since launch
Handled by Goldsky TurboEvery metric on the page is a count or a sum over transactions, so the history has to be complete.
Each transaction needs its sender, the contract it calls, its status, the gas it used and the fee paid, from your chain’s first block or from one start date applied to every chain. A chain loaded from a later date than the others looks smaller in every early month.
With Turbo Pipelines, a source on a chain’s
See the EVM datasets (opens in a new tab)raw_transactionsdataset set tostart_at: earliestreads it from the first block and keeps streaming new ones; each row carriesfrom_address,to_address,receipt_status,receipt_gas_used,receipt_effective_gas_priceand, where the chain reports it,receipt_l1_fee.Add the chains you compare against
Handled by Goldsky TurboReaders judge your chain’s growth against others, so those chains need the same history in the same tables.
Each chain needs the same columns and a chain label, so one query counts all of them. A new chain with no indexed dataset still has to be read from its own nodes.
Each comparison chain is another Turbo Pipelines source tagged with a chain column, and a chain Goldsky has no dataset for can stream from an RPC endpoint through an Edge EVM source, either Goldsky’s Edge RPC or your own archive node.
Stream any EVM chain from RPC (opens in a new tab)Land each transaction in your warehouse
Handled by Goldsky TurboAnalysts need one table of transactions per chain that they can query, label and rerun.
Each transaction is written once under its own key, and one removed by a reorg (the chain replacing its newest blocks) has to leave the table, or the counts include activity that never settled.
Goldsky’s ClickHouse sink, keyed on the transaction
Set up the ClickHouse sink (opens in a new tab)id, collapses repeated rows and marks rows a reorg removed as deleted; for Snowflake, BigQuery or Databricks, the S3 sink writes Parquet files the warehouse loads and dedupes on the same key.Strip bots and farmed addresses
Address counts are easy to inflate: one bot or airdrop farmer can run thousands of addresses.
Decide which addresses to leave out, such as known bots, addresses that only collect an airdrop and leave, and relayers that send on users’ behalf, and publish the rule with the figures. Where users act through smart accounts, the sender is a relayer, so count the account it acts for, which sits in the call or its events.
Count active, new and returning addresses
These are the headline growth numbers: how many addresses used the chain, how many were new and how many came back.
Count distinct senders per day, week and month, take each address’s first day as the day it was new, and group addresses by first month to see what share return in each later month. Rolling figures such as 30-day actives are window queries over the same table.
Total fees and usage per app
Fees show what users pay to use the chain, and usage per app shows where the activity is.
Sum gas used times the effective gas price, plus any L1 data fee, per day, and convert to dollars at the native token’s price for that day. Attribute each transaction to the app that owns the contract it calls, keeping in mind that a call routed through an aggregator or a smart account lands on that contract, not the app’s.
Report growth beside other chains
Foundations, builders and investors read the figures next to the chains they compete with.
Show each metric with its definition, chains and date range, so readers can compare it with figures from other sources, which often count active addresses differently.
What to know about streaming chain activity to your warehouse
- Goldsky runs the pipelines; your team owns the warehouse tables, the metric definitions and the dashboards.
- Distinct counts, cohorts and rolling windows such as 7-day actives are warehouse queries, so a new definition reruns over history without reloading it.
- Goldsky’s EVM datasets share one schema across chains; non-EVM chains carry different columns that you map to yours.
- A whole chain can’t be filtered down at the source, so loading its full history takes longer than loading a few contracts’ events.
Define each metric before counting
Active addresses, users and fees can each be counted several ways, and figures only compare across months and chains when the definition stays fixed.
Decide whether an active address is one that sends a transaction or also one that receives, whether failed transactions count, whether fees include the L1 data fee a rollup pays, and when an address counts as new or returning. Write the definitions down, because a chain that counts receivers looks larger than one that counts senders only.
Pick the comparison chains and label your apps
Growth means something next to a baseline, and usage per app needs to know which contracts belong to which app.
Choose the chains you compare against and one start date for all of them, and map the contracts on your chain to the apps that deployed them. A contract nobody labeled shows up as unknown usage instead of under its app.
Read every transaction on the chain
Handled by Goldsky TurboDaily counts and fees need every transaction, from the chain’s first block onward.
Each transaction needs its sender, the contract it calls, the fee paid and a day to count it under. A transaction counted under the wrong day moves activity between days and breaks daily charts.
A Turbo Pipelines source on your chain’s
See the EVM datasets (opens in a new tab)raw_transactionsdataset withstart_at: earliestreads from the first block and then follows new ones, and a SQL transform works out each transaction’s fee and sets a day column from its block timestamp.Keep daily counts per chain and contract
Handled by Goldsky TurboA dashboard needs current totals without rescanning every transaction.
Each transaction adds one to its day’s count and its fee to the day’s total, and one to the count for the contract it called; a transaction the chain removes is taken back out.
Goldsky’s Turbo Pipelines
Keep running totals in Postgres (opens in a new tab)postgres_aggregatesink keeps acountand asumof fees per day, and acountper contract and day, in Postgres tables a trigger updates on every insert, and subtracts a transaction when a reorg deletes it. Asumadds an updated row again instead of replacing it, so fee totals are a live view and the published figure comes from a recount.Keep one row per active address per day
Handled by Goldsky TurboActive, new and returning addresses all start from knowing which addresses were active on which day.
Grouping by sender and day turns every transaction into one row per address per day, small enough for a dashboard to query. A row whose count drops to zero after a reorg stays in the table, so queries count only rows above zero.
Another
Group running totals by key (opens in a new tab)postgres_aggregatesink in the same pipeline groups by sender and day with acount, so each address gets one row for each day it sent a transaction.Strip bots and farmed addresses
Address counts are easy to inflate: one bot or airdrop farmer can run thousands of addresses.
Decide which addresses to leave out, such as known bots, addresses that only collect an airdrop and leave, and relayers that send on users’ behalf, and publish the rule with the figures. Where users act through smart accounts, the sender is a relayer, so count the account it acts for, which sits in the call or its events.
Count actives, new addresses and retention
These are the headline growth numbers, worked out from the daily tables.
Your SQL counts rows per day for daily actives, takes each address’s earliest day as the day it was new, and groups addresses by first month to see how many come back. Rolling windows such as 30-day actives are queries over the same table.
Attribute usage and fees to apps
Usage per app shows which apps bring activity to the chain.
Join the per-contract counts to your app labels and convert daily fees to dollars at the native token’s price. Calls routed through an aggregator or a smart account count under that contract, not the app’s.
Recount before you publish
Running totals suit a live dashboard, but a figure you publish needs to match the chain exactly.
Check a published figure against a recount over the same period, from a table keyed on each transaction or from the chain itself. A gap is a repeated delivery or a corrected row the totals didn’t apply, and the recount is the one to trust.
What to know about running totals in Postgres
- Totals change as each block lands, and a transaction a reorg deletes is taken back out.
- A running
sumcan’t apply an updated row and a delivery repeated across checkpoints can count twice, so recount a figure before you publish it. - Distinct counts, retention and rolling windows are still your SQL, run on the daily tables instead of raw transactions.
- Each chain you compare adds its whole transaction stream to the database’s writes, and a whole chain’s history takes longer to load than a few contracts’ events.
What you control
- Your team
- Define each metric before counting
- Pick the comparison chains and label your apps
- Strip bots and farmed addresses
- Count active, new and returning addresses
- Total fees and usage per app
- Report growth beside other chains
Questions and answers
What are daily active addresses?
Daily active addresses are the number of distinct addresses that sent at least one transaction on a chain in a day. Definitions differ: some count receivers too, some drop failed transactions or known bots, so compare two figures only when they’re counted the same way. Where users act through smart accounts, the address that submits a transaction can be a relayer rather than the user.
Security and deployment
- SOC 2 Type IIIndependently audited security controls.
- Dedicated infrastructureSingle-tenant options for production workloads.
- Data residencyCloud, on-premises or co-located.
More use cases that analyze onchain activity
- Stablecoin transaction volume and market share by chainMeasure real stablecoin or tokenized-asset volume by chain, with inorganic flows stripped out.
- Track stablecoin issuers and competitors onchainFollow competitors’ and issuers’ supply, mints, burns and holders.
- Protocol financial statements from chain dataBuild income statements (fees, revenue and costs) for chains and apps from their contracts.
- Onchain research on listed crypto companiesTrack listed companies’ onchain revenue and users before they report earnings.
- Digital asset treasury company holdings and mNAVTrack what listed treasury companies hold onchain, per share, and their mNAV.
- Grant and incentive impact trackingMeasure what grants and incentive programs did to users, volume and TVL, per grantee.
- DAO delegate dashboards and voting power analyticsTrack voting power, delegators and votes per delegate for a token-governed DAO.
- Stablecoin market data for analytics: market cap, supply and activityTrack stablecoin supply and market cap by token, chain and issuer, with holders, active addresses, transfer counts and velocity over time.
Use cases built the same way
- NCUA stablecoin reporting dataReport supply, mint and burn, and holder figures for a stablecoin issued by a credit union subsidiary under the NCUA’s proposed rules.
- DAC8 and CARF reporting dataSupply the valued transfer history behind each user’s yearly DAC8 or CARF report.
- Onchain data for finance and BI reportingLoad onchain activity into the warehouse so finance and BI teams can report on it.
- Power a blockchain data productFeed a resold data product with multi-chain data and fast backfills.
Track blockchain ecosystem growth metrics with Goldsky
We’ll map it to your systems and show you what Goldsky runs, so your team builds the product, not the pipelines underneath it.
 Robinhood
 HyperEVM
 Arc
 Solana
 Ethereum
 Polymarket
 Base
 Tempo
 Bitcoin